AI agent development
Our AI agent development takes repetitive, multi-step work off your team and completes it inside the tools you already use. Every agent ships with approval steps, evals and monitoring, so you can see what it did and why.
AI agents services
- Agentic workflowsMulti-step agents that act across systems and pause for approval on the risky steps.
- Customer operations agentsAgents that draft, route and resolve support, claims and order questions.
- Internal copilotsAssistants for staff that answer from company knowledge and work with your tools.
- Voice agentsPhone and web voice agents for intake, scheduling and first-line support.
AI agents inside the software: Datum.
Datum is quoting and shop-floor software for sheet-metal and CNC suppliers with six AI agents built in, one task each: intake, follow-up, order status, purchasing, planning and quality. Each agent has a human owner, a monthly credit budget and an autonomy setting. Each shows what it proposed and how often that was accepted, adjusted or rejected.
The agents read freely and write only proposals. A drawing is read on intake, a morning briefing is written with the record behind every sentence, and nothing is sent, priced or ordered without a person. Read the full Datum case study.
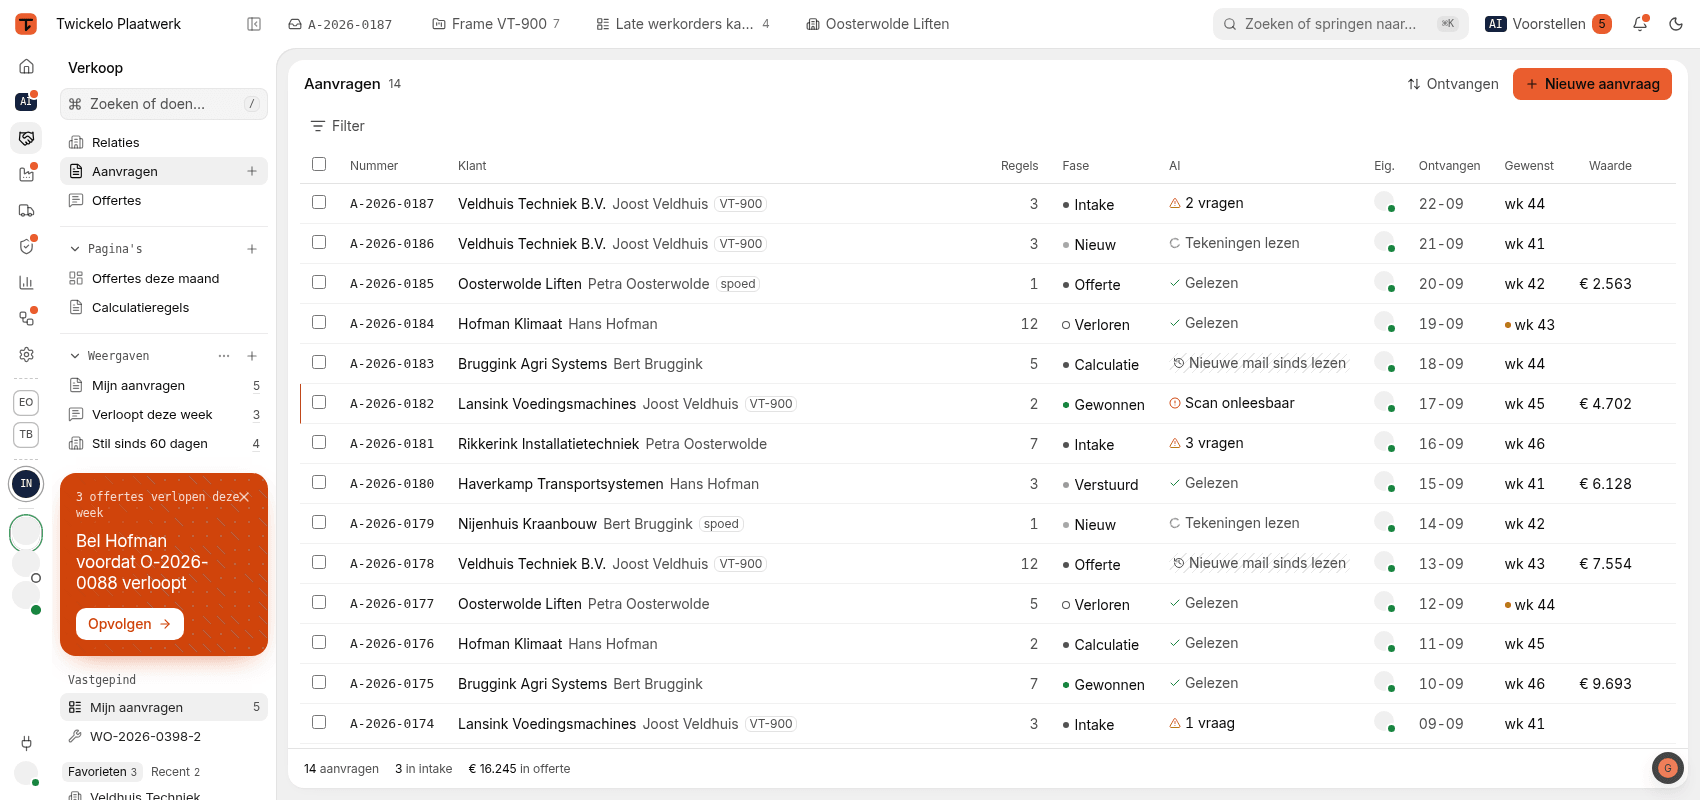
The work arrives. The AI column says what it did per request. Read, two questions, new mail since reading, or the scan was unreadable. Saying it cannot read something is part of the job.
It reaches the machine. One work order holds the drawing, the route, the hours booked against each operation and the outsourced step with its return date.
Six agents propose. Each agent has one task, a credit budget and an autonomy setting. The column that matters is what it proposed this week and how often that was taken, adjusted or refused.
The morning briefing. The briefing is written at half seven and every sentence carries the record it came from, so anyone can check it.
Screenshots show sample data.
How we work on it
Start from one process
We pick a single, well-understood process with measurable outcomes and make the agent reliable there before widening its scope.
People approve what matters
Approval steps are designed in from day one, and autonomy grows only where eval results and override rates justify it.
Evals before every release
Each agent has a test set built from real cases, and no prompt, model or tool change goes live until it passes.
Visible once it's live
Every run is traced with its inputs, tool calls, cost and outcome, so your team can answer what the agent did and why.
Related work
- Manufacturing
Quoting and shop-floor software where AI proposes and people decide
6agents, each with one task and a named owner- TypeScript
- React
- Hono
- Finance operations
Invoice approval that names the policy clause behind every decision
100%of automatic decisions cite a policy clause- AI agents
- Human in the loop
- RAG
- Logistics
Late shipments caught across every carrier, with the cause explained
€400ksaved a year- AI agents
- LangGraph
- Workflow automation
Built with
All technologiesFurther reading
What is an AI agent? Examples for businesses
An AI agent is software that carries out a task in several steps across your systems, within limits you set. What that means in practice, how it differs from a chatbot, three examples and when to build one yourself.
11 min read
Human-in-the-loop AI agents: design patterns for real operations
How we keep a human in the loop when AI agents run on live systems: approval checkpoints, confidence thresholds, tool permissions, audit trails and fallbacks.
5 min read
LLM evals: testing AI before every release
A practical approach to LLM evals: build a test set from real cases, combine code checks with model grading, and block releases that regress.
5 min read
Common questions
Software that uses a language model to decide which steps to take, calls tools such as your CRM, ERP or inbox to carry them out, and checks the result. The difference from a chatbot is that an agent completes work across systems.
Processes that repeat often, follow rules someone can explain, pull data from several systems and have outcomes you can check. Invoice handling, shipment exceptions, claims triage, lead research and ticket drafting are common examples.
We are model-agnostic and choose per task, usually from Anthropic Claude, OpenAI, Google Gemini or Mistral, and open models such as Llama when data must stay on your own infrastructure. Evals decide the choice, and we can switch models later without a rebuild.
We can run the full stack on EU infrastructure, including EU-hosted model endpoints, and keep logs and traces in your own cloud account. We document data flows so your security and privacy teams can review them.
It depends on the number of systems involved, the state of their APIs and how many edge cases the process has. We agree the scope and timeline after a short discovery phase, and release the agent in stages.
It depends mainly on the number of systems the agent works with, the quality of their APIs, how many exceptions the process has and how much of it needs a review screen. Model usage is usually the smaller part. We agree scope and timeline in a written plan after discovery.
No. Code, prompts, evals and infrastructure live in your own repositories and cloud accounts, documented so your own team or another supplier can take over.